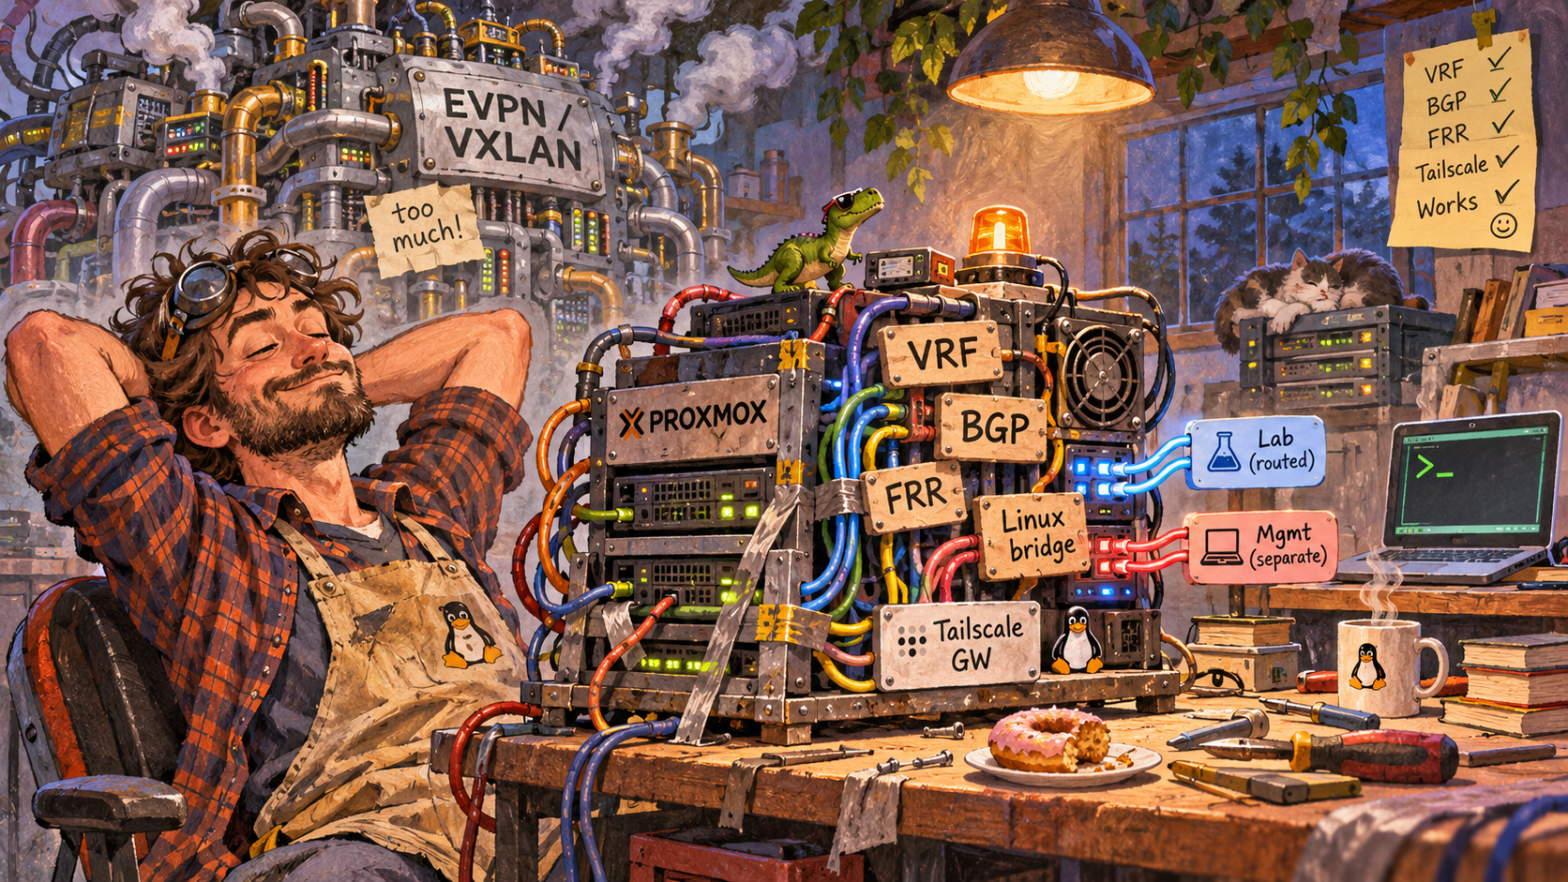
I’ve been spending a lot of time working with Proxmox lately, mostly because I keep finding things that it can do that I didn’t realize were possible. I’ve used VMware and NSX for a long time, and I tend to approach virtualization networking with a fairly specific set of expectations. There is the networking configuration the hypervisor manages, there is the networking configuration the underlying operating system manages, and generally speaking, mixing the two is a good way to have a bad afternoon.
Proxmox is a little different. Since the entire thing is built on Linux, there is a lot less separation between the virtual networking configuration and the actual networking stack. I knew that, obviously, but I hadn’t really appreciated how much you could take advantage of it until I started messing around with Proxmox SDN and FRRouting.
What started this whole project was a discovery that I probably should have made earlier: Proxmox can generate its SDN networking and FRR configurations while still allowing you to maintain custom configuration alongside them. You don’t have to give up control of the underlying network just because Proxmox is generating part of it.
Wait, I Can Do That?
When you create a network in Proxmox SDN, Proxmox is generating configuration for the Linux networking stack. Depending on what you’re doing, that might mean Linux bridges, VLANs, VXLAN interfaces, routing configuration, and FRR.
The SDN configuration lives under /etc/pve/sdn, and Proxmox translates that configuration into the files used by the underlying services. For Linux networking, that means interfaces generated under /etc/network/interfaces.d/sdn. For advanced routing, it can also mean generated FRR configuration. Ok so what? Well if you look at the main interfaces file you will see:
source /etc/network/interfaces.d/*
That means you can maintain additional interface configuration in separate files without directly modifying the SDN-generated file. There are some limitations to how Proxmox manages and validates networking, and you shouldn’t go creating competing definitions of the same interface, but the Linux networking stack itself doesn’t particularly care whether an interface came from the Proxmox GUI or a configuration file.
For example, suppose I wanted a dedicated VLAN interface for routing traffic between Proxmox and an external router. I could define something like this:
auto vmbr0.6iface vmbr0.6 inet static address 192.168.21.3/29
Assuming vmbr0 is VLAN-aware, that gives me a routed interface on VLAN 6. In fact, that is essentially what I’m doing in this environment. I have pfSense at 192.168.21.1, a MikroTik router at 192.168.21.2, and Proxmox at 192.168.21.3.
The same idea applies to FRR. Proxmox can generate FRR configuration for the networking features it manages, while frr.conf.local provides a mechanism for adding node-local routing configuration alongside Proxmox-generated configuration. For example, a custom BGP configuration could advertise a specific subnet to an external router:
ip prefix-list CUSTOM-NETWORKS seq 10 permit 192.168.50.0/24route-map CUSTOM-EXPORT permit 10 match ip address prefix-list CUSTOM-NETWORKSrouter bgp 65002 neighbor 192.168.21.1 remote-as 65001 ! address-family ipv4 unicast neighbor 192.168.21.1 activate neighbor 192.168.21.1 route-map CUSTOM-EXPORT out exit-address-family
That’s an example rather than a copy of my running configuration. You can’t blindly append arbitrary BGP configuration to an existing generated instance and expect everything to work. But it demonstrates how you can use Proxmox’s SDN automation and extend the routing functionality when the GUI doesn’t expose something you want. Again so what? Well that means I do do essentially whatever I want.
The Problem I Was Actually Trying to Solve
I wanted to use Proxmox SDN to create networks for VMs and containers, have those networks automatically routed, and advertise them to the rest of my network using BGP. I don’t want to create a new subnet in Proxmox and then go manually add a static route on pfSense, MikroTik, and whatever else needs to know about it. I want to create the network, assign a gateway, and have the routing infrastructure learn about it.
FRR makes that pretty straightforward. If Proxmox has an interface connected to 192.168.22.0/24, FRR can redistribute that connected route into BGP and advertise it to the other routers. The “problem” is where those routes live (Is it really a problem? Probably not but I’m special).
By default, Linux has a main routing table, and that’s where the host’s normal routes go. I don’t particularly want every route learned through BGP dumped into the same routing table that Proxmox uses for management traffic. My Proxmox host already has a management IP, a default gateway, and connectivity to everything it needs. I don’t need an external BGP router advertising a default route and potentially changing how the hypervisor itself reaches the network.
What I wanted was a separate routing domain for the SDN networks. Proxmox management would continue using the normal Linux routing table, while the SDN networks would have their own routing table, their own default route, and their own BGP sessions. Soooo….. VRF!
A VRF creates a separate routing context within the same operating system. Interfaces assigned to the VRF use its routing table, and FRR can run a BGP instance inside that VRF. The main routing table remains separate.
For this project, I used VRF vrf65002, Linux routing table 65002, and BGP AS 65002. There is no requirement for those numbers to match, but it makes the configuration a little easier to follow. You use what you want. You do you.
ip link add vrf65002 type vrf table 65002ip link set vrf65002 up
Now I have a VRF. The next step is getting Proxmox’s SDN networks into it.
Doesn’t Proxmox Already Do This with EVPN?
Yes. And this was probably the most interesting architectural decision in the whole project. Wait why am I trying to justify myself to you. Listen I do what I want and you do what you want. I am a crazy person? Yes. Is being crazy a good thing? Yes. You don’t agree with me? Well fine I’ll build my own SDN. With blackjack and hookers.
Proxmox already supports EVPN zones, and those zones use Linux VRFs to provide separate routing domains. So I absolutely could have used an EVPN zone to get the routing-table isolation I wanted.
An EVPN zone doesn’t just put everything into the host’s main routing table. It creates a dedicated VRF for the zone, and FRR can maintain the associated routing information separately from Proxmox management. Depending on the exit-node configuration, routes can also be deliberately leaked between the EVPN routing domain and the default routing table. Again you are asking questions. Why didn’t i just do that. See above…
Also EVPN solves a significantly larger problem than the one I had.
Proxmox EVPN zones are designed to provide virtual networking across multiple nodes using VXLAN and BGP EVPN. VNets are mapped to VXLAN VNIs, and the control plane distributes reachability information between participating hosts. An IP-VRF and Layer 3 VNI provide routed connectivity between VNets, while exit nodes provide connectivity to networks outside the EVPN environment.
That’s useful when you want to extend networks across multiple hypervisors, provide distributed gateways, and avoid making the physical network aware of every virtual subnet.
I wasn’t trying to extend Layer 2 networks between several Proxmox hosts. I didn’t need EVPN MAC/IP advertisements, distributed anycast gateways, or VXLAN tunnels. I had a single Proxmox host, existing physical routers, and ordinary IPv4 BGP connectivity.
I wanted local Linux bridges, with their connected routes inside a VRF, advertised to external routers.
There is an important difference in the uplink model too. Proxmox EVPN expects an underlay that can carry traffic between VXLAN endpoints. The EVPN control plane handles overlay reachability, and the zone’s exit-node functionality connects that routing domain to external networks. The standard exit-node approach can involve route leaking between the EVPN VRF and the default routing domain.
My design uses a physical VLAN interface, vmbr0.6, directly attached to the same VRF as the SDN bridges. The external routers peer with FRR running inside that VRF. There is no need to leak learned external BGP routes into the Proxmox management table.
Here’s how I looked at the two approaches:
| Capability | Proxmox EVPN zone | My Simple SDN + VRF |
|---|---|---|
| Separate routing table | Native | Custom Linux VRF |
| VNet-to-VRF membership | Native | Custom automation |
| Local VM network gateways | Yes | Yes |
| VXLAN encapsulation | Part of the design | Not needed |
| Multi-node L2 extension | Supported | Not provided |
| BGP control plane | BGP EVPN | IPv4 unicast BGP |
| External connectivity | Exit-node/fabric model | Direct routed VLAN uplink |
| Existing pfSense/MikroTik peers | Additional integration | Direct VRF BGP peers |
| Tailscale route exchange | Additional integration | Dedicated BGP gateway VM |
And here’s the detail that matters: even if I had chosen EVPN, the exact routing design I wanted would still have required custom configuration and potentially some scripting.
Proxmox would have handled the EVPN VRF, VXLAN network creation, and parts of the routing configuration for me. But it wouldn’t automatically know that I wanted my specific physical VLAN interface inside the same routing domain, peering with pfSense and MikroTik using my existing autonomous system assignments and route policies, while also exchanging routes with a Tailscale VM.
I could have extended the generated FRR configuration and built the additional integration around the EVPN zone. That was a perfectly reasonable technical possibility. But I would have been modifying and extending an already functioning SDN design to make it behave like something considerably simpler. Instead, I decided to implement exactly what I wanted.
Simple SDN already gave me the local bridges and subnets. Linux already provided VRFs. FRR already provided BGP. All I really needed was a way to connect those pieces so that Proxmox could continue managing the networks while my routing configuration stayed separate.
There was another advantage to that choice. I haven’t given up the option to deploy EVPN later.
Proxmox supports multiple SDN zones, so I can create an EVPN zone alongside my existing Simple SDN zone without replacing the current architecture. As long as I keep the routing domains, interfaces, VNIs, addressing, and FRR configuration from conflicting, both designs can coexist. Network reloads may still cause some disruption during configuration changes, but I don’t have to migrate the existing networks to EVPN just to experiment with it.
I can build an EVPN fabric for workloads that actually benefit from VXLAN and multi-node networking while leaving my existing routed Simple SDN design in place.
Building a VRF for Proxmox Simple SDN
The basic design is straightforward. Proxmox owns the SDN configuration, creates its bridges, and assigns their gateway addresses. My automation discovers which bridges belong to the zone and attaches them to the Linux VRF. FRR then sees the connected routes in that VRF and advertises them through BGP.
Here is the relevant Proxmox zone configuration:
simple: vrf65002 nodes pve
And a few VNets assigned to it:
vnet: netsvc zone vrf65002vnet: test zone vrf65002vnet: tail zone vrf65002
These correspond to several networks in the lab. netsvc has gateways for 192.168.11.0/24 and 192.168.12.0/24, test uses 192.168.22.0/24, and tail uses 192.168.24.0/30.
When Proxmox generates the network configuration, it creates ordinary Linux bridges. The tail bridge, for example, looks like this:
auto tailiface tail address 192.168.24.1/30 bridge_ports none bridge_stp off bridge_fd 0 ip-forward on
Nothing particularly unusual there. The bridge has an IP address, can be used as a gateway, and can have VM interfaces attached to it.
What it doesn’t have is:
vrf vrf65002
That missing line is the entire reason the custom integration exists.
I could manually attach the bridge:
ip link set tail master vrf65002
And its connected network would become part of routing table 65002. But that only solves the problem for a bridge that already exists. If I create another VNet tomorrow, I don’t want to SSH into Proxmox and configure it manually.
The automation needs to discover new VNets dynamically.
Making the VRF Follow the SDN Configuration
I ended up with a script called vrf65002-apply. Its job is to ensure the VRF exists, attach the BGP uplink, discover all VNets belonging to the SDN zone, and attach them.
The main discovery mechanism reads /etc/pve/sdn/vnets.cfg. That is important because it makes Proxmox’s own SDN configuration the source of truth. There is no separate list of bridge names that I need to update every time I create another network.
The important part of the attachment logic is reasonably simple:
attach() { local dev="$1" local current="" [ -e "/sys/class/net/$dev" ] || return 0 if [ -L "/sys/class/net/$dev/master" ]; then current="$(basename "$(readlink \ "/sys/class/net/$dev/master")")" fi [ "$current" = "$VRF" ] && return 0 [ -z "$current" ] || \ ip link set dev "$dev" nomaster || true ip link set dev "$dev" master "$VRF"}
It checks whether the interface exists, checks its current master, and does nothing if it’s already attached to the right VRF. Otherwise, it moves the interface into vrf65002.
The script also creates the VRF if necessary and installs an unreachable default route with a very high metric:
ip route add table 65002 unreachable default \ metric 4278198272
That route is a fallback. When FRR learns a valid default route from pfSense, the BGP route wins. If the BGP default disappears, the VRF has an unreachable default instead of relying on the host’s management routing table.
Getting the script to run at the right time required more than just calling it at boot. Proxmox creates and changes bridges during SDN Apply, so there are several opportunities for a VNet to exist after the initial startup script has already finished.
I used systemd services, a path watcher monitoring /etc/network/interfaces.d/sdn, and network-up hooks to reconcile the VRF when networking changes. The primary script also has a bounded wait mode to handle the gap between Proxmox writing its generated configuration and the bridges actually appearing.
This is probably more automation than I would like for something as simple as attaching bridges to a VRF, but it works with the version of Proxmox I’m running.
And it means that creating a new VNet in the zone is enough to make it eligible for the VRF automatically. There isn’t another manually maintained interface list.
Making FRR Route the Networks
Once the bridges are attached to the VRF, the FRR part is comparatively easy.
I created a BGP instance in vrf65002 using AS 65002, peering with pfSense, MikroTik, and eventually a Tailscale gateway VM.
The important configuration looks like this:
router bgp 65002 vrf vrf65002 bgp router-id 192.168.21.3 no bgp default ipv4-unicast neighbor 192.168.21.1 remote-as 65001 neighbor 192.168.21.2 remote-as 65000 neighbor 192.168.24.2 remote-as 65003 neighbor 192.168.24.2 ebgp-multihop 5 ! address-family ipv4 unicast redistribute connected route-map VRF65002-EXPORT neighbor 192.168.21.1 activate neighbor 192.168.21.1 route-map VRF65002-IMPORT in neighbor 192.168.21.1 route-map VRF65002-EXPORT out neighbor 192.168.21.2 activate neighbor 192.168.21.2 route-map VRF65002-IMPORT in neighbor 192.168.21.2 route-map VRF65002-EXPORT out neighbor 192.168.24.2 activate neighbor 192.168.24.2 route-map VRF65002-IMPORT in neighbor 192.168.24.2 route-map VRF65002-EXPORT out exit-address-family
The key command is redistribute connected. FRR doesn’t need an individual network statement for each subnet. Once a bridge is attached to the VRF and its connected route appears in table 65002, FRR can automatically originate that network into BGP, assuming the route map permits it.
I also created export filtering to prevent the BGP peering subnet itself from being advertised back toward the routers:
ip prefix-list VRF65002-EXPORT seq 5 deny 192.168.21.0/29ip prefix-list VRF65002-EXPORT seq 100 permit 0.0.0.0/0 ge 1 le 32
That permits non-default IPv4 prefixes other than the peering subnet. It’s deliberately broad for this lab, and something I’d tighten considerably in a production environment. The import map is also permissive, so this isn’t an example of a particularly restrictive routing policy. But it demonstrates the mechanism. I can create a new subnet in Proxmox SDN, apply the configuration, have the bridge attached to vrf65002, and have its connected route appear in BGP without manually adding anything to FRR. Meanwhile, Proxmox management traffic still uses the main routing table and its normal default gateway.
Or is it????
Tailscale Time or Why Not Just Run Tailscale on pfSense?
This is the obvious question, because I was already running pfSense, and Tailscale has a pfSense package. Why create another VM, install another copy of FRR, and add another BGP peer when I already have a router that can do all of this?
I had been using Tailscale on pfSense, and I wasn’t particularly happy with how the routing was behaving. When I was away from home, there were occasions when I could connect to the VPN but couldn’t reach internal resources that should have been accessible. That’s a particularly annoying failure because the VPN appears to be working. You’re connected, Tailscale is running, and yet the thing you actually connected to access is unavailable.
I hadn’t conclusively isolated the cause of every one of those failures, but it had become something I didn’t particularly trust. And troubleshooting it remotely, especially when the routing device you’re debugging is also responsible for the rest of your network, isn’t my idea of a good time. Honestly I didn’t even try.
There was also a more fundamental limitation with Tailscale on pfSense. pfSense is based on FreeBSD, and Tailscale’s subnet-routing implementation on non-Linux platforms uses its userspace network stack. For the supported configuration I was using, subnet traffic is effectively proxied through the Tailscale router, with connections appearing to originate from that router rather than preserving the actual source address.
Tailscale’s --snat-subnet-routes=false option is supported on Linux, not FreeBSD. And I specifically wanted to avoid subnet SNAT.
That distinction matters to me. With SNAT, the internal device sees the subnet router as the source of the traffic. That’s convenient because it reduces the need to configure return routes, but it also hides the actual source address. You lose visibility into which remote device initiated the connection, and it makes it harder to apply routing and firewall policy based on the original address.
I wanted full routed connectivity, with the original source and destination addresses preserved. I wanted the other networks to know how to reach the Tailscale networks, and I wanted Tailscale to know how to reach them in return.
I could have continued trying to make pfSense do what I wanted, and there are experimental FreeBSD networking approaches that might eventually address some of those limitations. But I was already using Proxmox, Linux VRFs, and FRR. Moving Tailscale into a dedicated Linux VM gave me the routing behavior I wanted without fighting the FreeBSD implementation.
It also separated Tailscale from the primary firewall. pfSense could continue being my firewall and BGP router, while the Tailscale VM became a dedicated gateway between the tailnet and the rest of the network. If I wanted to inspect the routes, capture packets, change FRR policies, or restart Tailscale, I could do that independently without making changes to the main firewall.
Is that actually easier to troubleshoot? I don’t know. I’ve added another VM, another BGP session, another routing table, and another set of opportunities to do something stupid. From a pure component-count perspective, I’ve probably made things more complicated.
But I like it better.
I can look at the Linux routing tables, inspect Tailscale’s policy rules, and see exactly which networks FRR is advertising. I can make changes to the Tailscale gateway without wondering whether I’m also going to break the firewall that the rest of my house depends on.
Whether that’s simpler is debatable. Whether I’d rather troubleshoot it this way isn’t.
Connecting Tailscale to the VRF
With the decision made to move Tailscale onto Linux, I created a dedicated VM attached to the tail VNet. The VM has 192.168.24.2/30, uses Proxmox at 192.168.24.1 as its gateway, and runs its own FRR instance in AS 65003. The Tailscale VM establishes an eBGP multihop session with the Proxmox BGP instance at 192.168.21.3. On the Proxmox side, routes learned from Tailscale appear in vrf65002 alongside routes learned from pfSense and MikroTik.
Tailscale introduces a separate routing challenge because it uses Linux policy routing and normally installs accepted routes into table 52. Those routes aren’t automatically visible to FRR’s main routing table. FRR has a useful feature for exactly this sort of situation:
router bgp 65003 address-family ipv4 unicast redistribute table-direct 52 route-map TAILSCALE-TO-BGP exit-address-family
That allows the Tailscale VM to import selected prefixes directly from table 52 into BGP without first copying them into the main routing table. In my case, I filtered the redistribution to permit 192.168.1.0/24, while explicitly excluding 192.168.10.0/24, which was also reachable through the physical BGP network.
Why exclude it? Because during testing, I managed to get Tailscale and BGP advertising overlapping networks to one another. FRR then started locally originating a route it had already learned from another BGP peer, which changed best-path selection and removed the expected BGP route from the Linux main table.
The result was predictable in hindsight. Traffic went somewhere I hadn’t intended, and my SSH session wasn’t particularly interested in continuing the conversation. The filtering addressed the route feedback, but I also added a Linux policy-routing rule to prefer specific routes from the main table before Tailscale routes:
ip rule add pref 2500 lookup main suppress_prefixlength 0
That suppress_prefixlength 0 is doing something useful. It prevents the main table’s default route from winning during that early lookup, while still allowing more-specific routes, including BGP routes, to take precedence over Tailscale’s table 52.
If the main table doesn’t have a specific route, Tailscale can still provide one. And if neither has one, the normal default route remains available later in the policy-routing sequence. I also advertised selected BGP-side subnets into Tailscale so remote tailnet nodes could route traffic back toward the Proxmox networks. For this configuration, I disabled Tailscale subnet SNAT because I wanted the real source addresses preserved across the routed networks. The result is that Proxmox can learn 192.168.1.0/24 from Tailscale through BGP, while the Tailscale gateway knows how to reach the Proxmox-side networks through its own BGP routing.
It turns the Tailscale VM into an ordinary routed connection between the tailnet and the rest of the network.
The Part That Still Doesn’t Work Quite Right
There is one remaining annoyance in this implementation, and it comes directly from the fact that my VRF integration lives outside Proxmox’s generated interface configuration.
When I click SDN Apply, Proxmox uses ifupdown2 to reconcile the running Linux network against the generated configuration. The problem is that ifupdown2 doesn’t see the VRF membership that my scripts added.
For example, Proxmox generates the tail interface without a VRF definition. My script attaches it to vrf65002. When ifupdown2 reloads the interface, it sees an interface attached to a master that isn’t represented in the configuration.
During investigation, I ran a dry run of the network reload:
ifreload -a -n -v
The output was pretty revealing. For tail, ifupdown2 planned operations including:
ip link set dev tail nomasterip link set dev tail downip link set dev tail up
It did essentially the same thing to the physical BGP interface vmbr0.6 and the other SDN bridges. Then I captured an actual SDN Apply using Linux netlink monitoring and the FRR logs. The physical BGP sessions to pfSense and MikroTik went down with an Interface down event and reestablished shortly afterward. FRR itself never restarted. The bgpd and zebra processes remained running throughout the operation. The interfaces underneath them were being reconfigured.
The Tailscale BGP neighbor actually survived one of the reloads, while the two peers using vmbr0.6 reset. That was a useful distinction because it established that the problem wasn’t a complete restart of FRR or a global BGP configuration failure.
My scripts restore the VRF attachment afterward, so the networks recover. But there is still a brief disruption while ifupdown2 detaches and reattaches the interfaces. I considered using BGP graceful restart, but that doesn’t actually fix what is happening. Graceful restart can help preserve routing information during certain control-plane interruptions. It doesn’t magically keep packets flowing through an interface that Linux has just taken down. The cleaner solution is to have ifupdown2 know that the interfaces belong to the VRF in the first place.
Proxmox May Be Fixing This for Me
While investigating, I found a Proxmox development patch series proposing native VRF support for Simple SDN zones.
The proposed design is very close to what I’ve implemented manually. Instead of requiring external scripts to create a VRF and attach bridges to it, a Simple zone could use a dedicated Linux VRF, with Proxmox generating the VRF membership as part of the network configuration.
That would make a substantial difference because the generated configuration would contain the information that ifupdown2 currently lacks. There are still some complications for my environment. The proposed implementation uses a generated VRF name based on the zone and automatic routing-table allocation. My existing configuration uses the explicit name vrf65002 and table 65002. I also have a physical BGP peering interface and custom FRR policies.
The patch also introduces VRF-aware fabric routing integration, which could potentially replace more of the custom routing configuration. But I don’t really want to redesign the whole thing just because a new feature becomes available. But I probably will.
My plan is to leave the current implementation running until native Simple-zone VRF support is released, then evaluate whether it can replace the attachment automation while keeping the existing BGP behavior. The patch was still under development when I investigated it, so I wouldn’t treat it as an available feature in my installed Proxmox 9.2 environment.
Where This Ended Up
What I like about this project is that it demonstrates how much flexibility you get from Proxmox being built on standard Linux networking. The original requirement wasn’t particularly exotic. I wanted a collection of VM networks with their own routing table, dynamically advertised through BGP, without interfering with the hypervisor’s management networking. EVPN could have supplied the VRF isolation, and with additional work I could probably have integrated my existing BGP environment into it. But I would have been introducing VXLAN and the EVPN control plane, then doing custom work to make that architecture behave the way I wanted.
Instead, I used a Simple SDN zone, a Linux VRF, shell scripts, systemd services, FRR, and eventually a Tailscale gateway. The custom work went directly into the functions I needed, and I can still deploy an independent EVPN zone later if I find a reason to use one.
The Tailscale VM is a similar decision. Running it on pfSense would have meant fewer components, but it also meant living with the FreeBSD subnet-routing limitations and continuing to troubleshoot VPN connectivity on my primary firewall. Moving it to Linux gave me full routed connectivity without subnet SNAT and a separate place to investigate problems.
There are still rough edges. The custom VRF attachment isn’t visible to ifupdown2, SDN Apply can briefly disrupt the network, and there are more moving parts than I’d prefer. The scripts could also use some cleanup and stronger error handling.
But I don’t have to manually maintain routes for every new VM network. I don’t have to push SDN routes into the Proxmox management routing table. And I don’t have to deploy an EVPN fabric just to get routed connectivity between a few local networks and the rest of my infrastructure.
Perhaps the most useful discovery was how Proxmox lets you extend its generated networking configuration with the underlying Linux and FRR capabilities. There is a lot more available than what appears in the SDN interface, provided you’re willing to understand how the pieces fit together.

